The next generation of open-weight natively multimodal large language models
Interactive Guide ~30 minLLAMA4 represents Meta's most advanced AI models to date, designed as natively multimodal models that can process both text and images with exceptional performance. The LLAMA4 herd introduces mixture-of-experts architectureA technique that divides tasks into smaller jobs and assigns each to specialized neural networks, achieving better performance with fewer active parameters — providing breakthrough capabilities while maintaining efficiency.
LLAMA4 (Large Language and Multimodal AI) is Meta's most advanced suite of AI models, building upon the success of previous Llama generations. Released on April 5, 2025, LLAMA4 represents a significant leap forward in AI capabilities, introducing the first open-weight natively multimodal models with unprecedented context length support and the company's first built using a mixture-of-experts (MoE) architecture.
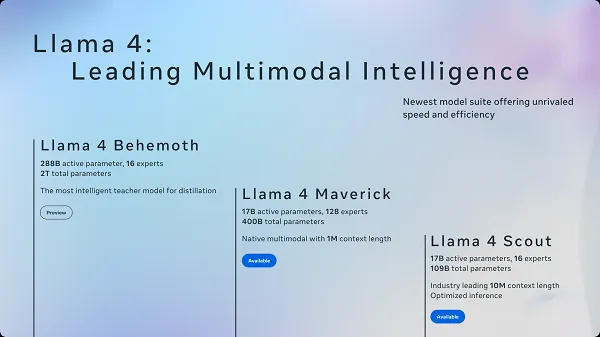
LLAMA4 introduces three models in its herd: Scout, Maverick, and Behemoth (still in training). Each model is designed for different use cases while sharing the core capabilities of multimodal understanding and advanced reasoning.
Unlike previous generations, LLAMA4 models are built with native multimodality from the ground up, incorporating early fusion to seamlessly integrate text and vision tokens into a unified model backbone.

LLAMA4 continues Meta's commitment to open AI development, making the models available for commercial and research use under the Llama 4 Community License. This approach enables developers, researchers, and enterprises to build upon these advanced models for various applications while encouraging innovation in the AI ecosystem.
The LLAMA4 herd currently consists of two publicly available models—Scout and Maverick—each designed with specific strengths and use cases in mind. A third model, Behemoth, is still in training and serves as a teacher for the smaller models.
The efficient specialist with unprecedented context length
The performance powerhouse with advanced multimodal capabilities
The massive teacher model powering the next generation of AI

LLAMA4 introduces several groundbreaking features that set it apart from previous generations and competing models. These innovations enable new capabilities and use cases while maintaining efficient operation.
LLAMA4 uses a mixture-of-experts approach where each token activates only a subset of parameters, making models more efficient while maintaining high performance.
Built with early fusion to seamlessly integrate text and vision tokens, enabling sophisticated image understanding without specialized connectors.
LLAMA4 Scout offers an industry-leading 10M token context window, nearly 80 times larger than Llama 3's 128K tokens.
Pre-trained on 200 languages with 10x more multilingual tokens than Llama 3, supporting 12 major languages with deep fluency.
Significantly improved coding capabilities, outperforming GPT-4o on many coding benchmarks and supporting complex programming tasks.

Best-in-class image grounding capabilities, allowing precise visual question answering and object localization within images.
Advanced quantization techniques enable deployment on consumer-grade hardware without significant performance degradation.
Built with comprehensive safety features and protections, including reduced political bias and improved refusal handling.
One of the key innovations in LLAMA4 is the iRoPE architecture (interleaved attention layers without positional embeddings), which enables the unprecedented context window length:
LLAMA4 uses alternating dense and mixture-of-experts layers for inference efficiency. In Maverick, each token is sent to a shared expert and one of 128 routed experts.
LLAMA4 employs inference time temperature scaling of attention to enhance length generalization, enabling the processing of extremely long documents.
LLAMA4 models incorporate cutting-edge AI technologies and architectural innovations. Here are the detailed technical specifications for each model in the LLAMA4 family:
| Specification | LLAMA4 Scout | LLAMA4 Maverick |
|---|---|---|
| Model Architecture | Auto-regressive with MoE, early fusion multimodal | Auto-regressive with MoE, early fusion multimodal |
| Active Parameters | 17 billion | 17 billion |
| Total Parameters | 109 billion | 400 billion |
| Expert Structure | 16 experts | 128 experts |
| Context Window | 10 million tokens | 1 million tokens |
| Pretraining Tokens | ~40 trillion | ~22 trillion |
| Supported Languages | Arabic, English, French, German, Hindi, Indonesian, Italian, Portuguese, Spanish, Tagalog, Thai, Vietnamese | Arabic, English, French, German, Hindi, Indonesian, Italian, Portuguese, Spanish, Tagalog, Thai, Vietnamese |
| Input Modalities | Multilingual text and images | Multilingual text and images |
| Output Modalities | Multilingual text and code | Multilingual text and code |
| Multi-image Support | Up to 8 images tested, 48 in training | Up to 8 images tested, 48 in training |
| Knowledge Cutoff | August 2024 | August 2024 |
| Hardware Requirements | Single H100 GPU with int4 quantization | Single H100 DGX host with FP8 quantization |
| License | Llama 4 Community License | Llama 4 Community License |

LLAMA4 models implement the mixture-of-experts architecture in different ways:
LLAMA4's native multimodality uses an improved vision encoder:
The LLAMA4 models can be quantized to different precision levels to balance performance and computational requirements. The official release includes BF16 weights for Scout and both BF16 and FP8 quantized weights for Maverick, with code provided for on-the-fly int4 quantization.
LLAMA4 models have demonstrated exceptional performance across a wide range of benchmarks, often outperforming much larger models from competitors. Here's how LLAMA4 Scout and Maverick stack up in various categories:
| Benchmark | Llama 3.1 70B | Llama 4 Scout | Llama 4 Maverick |
|---|---|---|---|
| MMLU | 79.3 | 79.6 | 85.5 |
| MMLU-Pro | 53.8 | 58.2 | 62.9 |
| MATH | 41.6 | 50.3 | 61.2 |
| MBPP (Code) | 66.4 | 67.8 | 77.6 |
| TydiQA | 29.9 | 31.5 | 31.7 |
| Benchmark | Llama 3.3 70B | Llama 4 Scout | Llama 4 Maverick |
|---|---|---|---|
| MMLU Pro | 68.9 | 74.3 | 80.5 |
| GPQA Diamond | 50.5 | 57.2 | 69.8 |
| LiveCodeBench | 33.3 | 32.8 | 43.4 |
| MGSM | 91.1 | 90.6 | 92.3 |

| Benchmark | Llama 4 Scout | Llama 4 Maverick |
|---|---|---|
| MMMU | 69.4 | 73.4 |
| MMMU Pro | 52.2 | 59.6 |
| MathVista | 70.7 | 73.7 |
| ChartQA | 88.8 | 90.0 |
| DocVQA | 94.4 | 94.4 |
| Benchmark | Llama 3.3 70B | Llama 4 Scout | Llama 4 Maverick |
|---|---|---|---|
| MTOB (half book) eng→kgv | Context window is 128K | 54.0 | 42.2 |
| MTOB (half book) kgv→eng | Context window is 128K | 46.4 | 36.6 |
| MTOB (full book) eng→kgv | Context window is 128K | 50.8 | 39.7 |
| MTOB (full book) kgv→eng | Context window is 128K | 46.7 | 36.3 |
In comparative benchmarks, LLAMA4 models show remarkable performance against top competitors:

LLAMA4 Behemoth, still in training, is showing even more impressive results, outperforming GPT-4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on several STEM benchmarks. Its performance as a teacher model has significantly enhanced the capabilities of both Scout and Maverick through distillation.
Getting started with LLAMA4 is straightforward, with multiple options for deployment and usage depending on your needs and technical capabilities. Here's how you can start using LLAMA4 models:
Access LLAMA4 through leading cloud service providers with pre-configured environments.
Download and run LLAMA4 models on your own infrastructure for maximum control.
Try LLAMA4 through Meta's applications without any setup required.
Decide whether to use cloud services, local installation, or pre-built applications based on your use case and technical requirements.
Choose between LLAMA4 Scout for long context handling and efficiency, or LLAMA4 Maverick for superior performance and advanced reasoning.
If self-hosting, ensure you have the necessary hardware (H100 GPU or equivalent) and follow the installation instructions from llama.com or GitHub.
Configure system prompts, adjust generation parameters, and implement safety measures according to your specific requirements.
Integrate LLAMA4 into your applications using the provided APIs or SDKs, and deploy to your users or internal systems.
LLAMA4 models support multimodal inputs, allowing you to process both text and images:
Remember that LLAMA4 models are covered by the Llama 4 Community License, which allows for commercial and research use with certain restrictions. Be sure to review the license terms and ensure your usage complies with Meta's acceptable use policies.
LLAMA4's advanced capabilities enable a wide range of innovative applications across industries. Here are some of the key use cases where LLAMA4 models excel:
LLAMA4 assists developers with code generation, debugging, and documentation, understanding entire codebases with its extensive context window.
Leverage LLAMA4's multimodal capabilities for chart interpretation, data summarization, and insight generation from diverse data sources.
Transform educational experiences with personalized tutoring, research assistance, and comprehensive content creation.
Enhance medical research, patient care, and health informatics with LLAMA4's advanced reasoning and multimodal capabilities.
Generate high-quality written content, analyze visual media, and create comprehensive multimedia materials for various platforms.

The unprecedented 10M token context window of LLAMA4 Scout enables entirely new types of applications:
Process and analyze entire books or multiple research papers in a single context, maintaining coherence across the full text.
Compare and contrast multiple lengthy documents, identifying similarities, differences, and patterns across the entire corpus.
Analyze complete codebases with millions of lines, understanding architectural patterns and dependencies holistically.
Maintain context over extremely long conversations, remembering details from hours of previous interaction.
LLAMA4's open-weight approach enables developers and organizations to build innovative applications with state-of-the-art AI capabilities. Whether you're creating consumer applications, enterprise solutions, or research tools, LLAMA4 provides the performance and flexibility you need.
LLAMA4 introduces several major innovations: it's the first Llama model to use a mixture-of-experts architecture, it's natively multimodal with early fusion of text and images, it offers unprecedented context lengths (up to 10M tokens), and it's trained on significantly more data (up to 40T tokens).
Choose Scout if you need extremely long context handling (10M tokens), have hardware constraints, or are processing large documents. Choose Maverick for state-of-the-art performance in multimodal tasks, advanced reasoning, and production-grade applications where you can support more powerful infrastructure.
LLAMA4 Scout can run on a single H100 GPU with int4 quantization, while LLAMA4 Maverick requires a single H100 DGX host with FP8 quantization. Alternative options include using cloud providers that offer LLAMA4 as a service, which eliminates the need for specialized hardware.
LLAMA4 officially supports 12 languages: Arabic, English, French, German, Hindi, Indonesian, Italian, Portuguese, Spanish, Tagalog, Thai, and Vietnamese. However, it was pre-trained on 200 languages, including over 100 with more than 1 billion tokens each, so it has capabilities in many additional languages.
Yes, LLAMA4 is available under the Llama 4 Community License, which allows for commercial use with certain restrictions. You can use LLAMA4 in commercial applications as long as you comply with the license terms and Meta's acceptable use policies.
LLAMA4 Behemoth is still in training and Meta has not announced a specific release date. It currently serves as a teacher model for Scout and Maverick, and Meta has shared that it outperforms models like GPT-4.5 and Claude Sonnet 3.7 on several STEM benchmarks.
Join the growing community of developers, researchers, and organizations leveraging LLAMA4's advanced capabilities to create the next generation of AI applications.
Meta's most advanced open-weight natively multimodal large language models, designed to enable the next generation of AI applications.
© 2025 Meta AI. LLAMA4 is a registered trademark of Meta. All images used are from public sources.